Projects/2025/live
Adaptive Video Transcoder
A scalable, event-driven video transcoding pipeline enabling Adaptive Bitrate Streaming for video platforms.
- FastAPI
- PostgreSQL
- FFmpeg
- HLS
- AWS Lambda
- SQS
- S3
- ECS
- ECR
A video platform is only as good as its worst network condition. This project is a transcoding pipeline that takes a single uploaded master video and turns it into a ladder of renditions, so every viewer gets a smooth stream whether they are on fibre or a patchy mobile connection.
Why it needs to be adaptive
Video is where “smooth” gets tested, because the same master file has to play on any device and any bandwidth. Hand a player one heavy file and a slow connection and you get buffering. Hand it nothing at all and the situation is worse: the viewer has to download the whole video before playback starts. Picture a 1 GB file on a 2 Mbps connection. That is not a video, it is a progress bar.
Transcoding fixes this by producing a ladder of standard renditions (1080p, 720p, 480p, 360p, 144p), so there is always a version that fits the connection. FFmpeg splits each rendition into short segments, and the player fetches those segments as it plays, picking a rendition that matches the bandwidth it has right now. That grey sliver ahead of the playhead on YouTube is exactly this: the next segments arriving before you need them. At 3 Mbps or better the player holds 1080p without stalling; below that it steps down instead of freezing.
How it works
Uploads land in S3, which emits an event that enqueues a transcoding job on SQS. Serverless workers on AWS Lambda pick jobs off the queue, run FFmpeg to transcode the master into multiple bitrates, and segment the output into HLS playlists. Containerized services deployed on ECS (pulled from ECR) handle the longer, heavier jobs that outlive Lambda’s execution window. Metadata (status, renditions, playback URLs) is served by a FastAPI service with PostgreSQL behind it.
System design
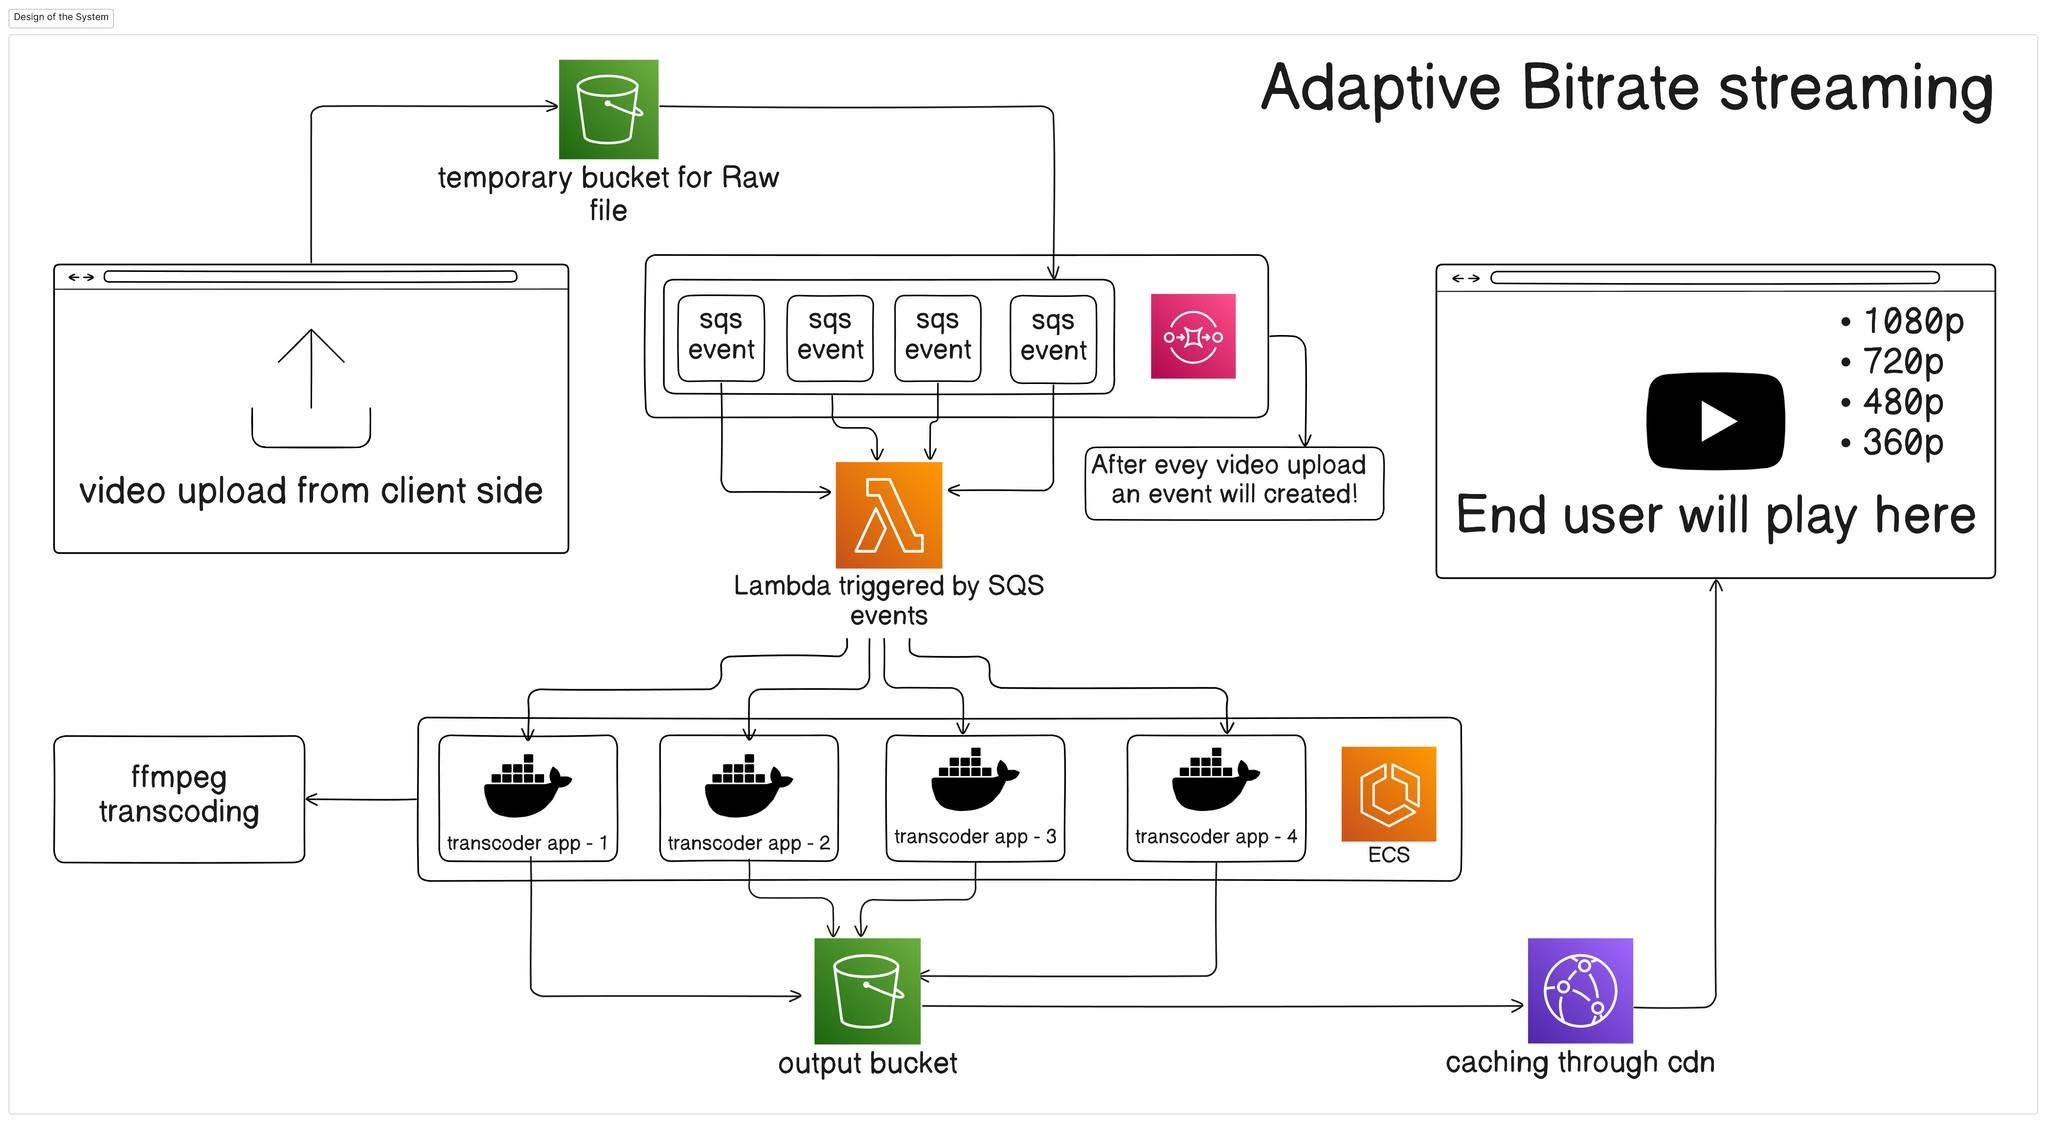
Figure: the metadata API on top, the AWS pipeline underneath. Uploads to S3, jobs queued on SQS, Lambda reacting to new objects, and ECS containers running FFmpeg to produce the HLS ladder.
The flow, step by step
- Ingest: the client asks the API for a pre-signed URL and uploads the master straight into the raw S3 bucket, so the API layer never proxies video bytes.
- Queue: the bucket’s object-created event becomes a message on SQS. The upload request is already finished; the work is now a queue entry with its own retry and visibility rules.
- Dispatch: a Lambda consumer reads the message, records the job in PostgreSQL, and starts the transcoding task on ECS, because a full rendition ladder takes longer than a function invocation should live.
- Transcode: the ECS container pulls the master, runs FFmpeg once per rendition from 1080p down to 144p, and cuts each output into segments at aligned keyframes so a player can switch quality mid-stream without glitches.
- Package: segments and the HLS playlists are written to the processed bucket, and the job row moves to ready with the manifest key.
- Play: the API hands the player a manifest URL. The player opens on a conservative rendition and climbs as measured bandwidth allows, stepping back down instead of stalling when it doesn’t.
Design decisions
- Event-driven over cron-driven: SQS decouples ingestion from processing, so spikes in uploads queue up instead of toppling the system.
- Serverless for the bursty part: Lambda scales to zero when idle and fans out under load without capacity planning.
- Adaptive Bitrate Streaming: FFmpeg produces a rendition ladder and HLS manifests, letting players switch quality mid-stream as network conditions change.
- Containers for the long tail: ECS absorbs transcoding jobs too heavy for Lambda’s limits, keeping the architecture heterogeneous but simple.
What I learned
Designing for failure at queue level changes everything: retries, dead-letter queues, and idempotent workers turned out to matter more than raw transcoding performance.
What’s next
- Signed playback URLs so private videos stay private end to end.
- Job state in the API: progress, retries and dead-letter failures visible to the client instead of only inside the queue.
- Cost per rendition tracked, to decide what belongs on Lambda and what earns a container.
- Thumbnails and preview sprites generated by another consumer of the same queue, rather than a second pipeline.